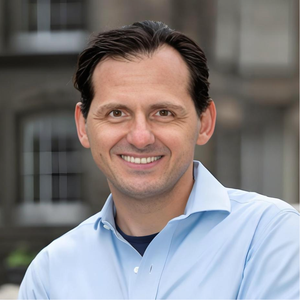
专题演讲嘉宾:Gregor Hofer 博士

Rapport and Speech Graphics联合创始人 & CEO

Gregor Hofer has a wealth of industry knowledge as well as a strong academic background,holding a PhD in informatics from the University of Edinburgh. He was a senior researcher at the Telecommunications Research Centre in Vienna and a research fellow at the School of Informatics before co-founding Speech Graphics. It was then that he developed text-to-speech artificial intelligence and commercialised a prototype that is currently utilised on official websites.

Gregor co-founded Speech Graphics with Michael Berger and gaming industry veteran Colin Macdonald in 2010 to commercialize voice-activated facial animation. Since then, the group has won numerous honours, such as the John Logie Baird Award for innovation and the 2022/2023 TIGA Award for Best Technology Supplier.

As an extension of  Speech Graphics Gregor launched Rapport in 2024, with the goal of specialising in emotionally intelligent virtual interactive personas. In addition to his full-time role at Speech Graphics,, Gregor is also Supervisory Board member at System Industrie Electronic Holding AG.

Gregor Hofer 拥有深厚的行业经验和扎实的学术背景,持有爱丁堡大学信息学博士学位。在联合创办 Speech Graphics 公司之前,他曾担任维也纳电信研究中心高级研究员及信息学院研究员。同期,他研发了文本转语音人工智能技术,并将一款原型产品商业化,该产品目前已应用于多个平台。

2010 年,Gregor Hofer 与 Michael Berger 以及游戏行业资深人士 Colin Macdonald 共同创办了 Speech Graphics,致力于将声控面部动画技术商业化。自成立以来,该公司斩获多项荣誉,包括表彰创新成就的约翰・洛吉・贝尔德奖以及 2022-2023 年度 TIGA 最佳技术供应商奖。

2024 年,Gregor Hofer 在 Speech Graphics 的业务基础上推出了 Rapport,旨在专注于研发具备情感智能的虚拟交互形象。除了在 Speech Graphics 担任全职工作外,格雷戈尔同时也是 System Industrie Electronic Holding AG 的监事会成员。


by Gregor Hofer 博士

Rapport and Speech Graphics
联合创始人 & CEO

The next wave of AI combines language, behavior, and embodiment into a single interface with voice, personality, and presence. As AI evolves beyond text generation toward emotionally responsive, multimodal systems, Visual Conversational AI is poised to redefine how we work, learn, and engage. This session explores the underlying technologies such as real-time behaviour modelling that power lifelike avatars, and how they enable a shift from static conversational bots to fully interactive digital beings capable of speaking and listening in a lifelike manner.

人工智能的下一波浪潮将语言、行为和具身化整合到一个集声音、个性与存在感于一体的界面中。随着人工智能从文本生成向具备情感响应能力的多模态系统演进,视觉对话式人工智能正蓄势待发,重新定义我们的工作、学习与互动方式。本环节将深入探讨支撑逼真虚拟形象的底层技术(如实时行为建模),以及这些技术如何推动人工智能从静态对话机器人向能够以逼真方式进行听说互动的全交互式数字 “生命体” 转变。

Presentation Outline

1. The Next Wave of AI — From Text to Multimodal Interaction

  • Why Visual Conversational AI Matters Now
  • From Bots to Beings — A Shift in Human–AI Interaction

2. Core Technologies Behind Lifelike Avatars

  • Real-time behaviour modelling
  • Speech synthesis & emotional prosody
  • Facial animation & physical motion

3. The Power of Embodiment — Voice, Personality, and Presence

4. Emotional Responsiveness in AI

5. Use Cases Transforming Work, Learning & Engagement

6. The Trust Factor — Why Lifelike Interactions Drive Better Outcomes

7. Challenges & Considerations — Latency, Realism, Technical Expertise

8. The Future is Interactive — A Vision for Visual Conversational AI

演讲提纲

1. 人工智能的下一波浪潮 —— 从文本到多模态交互

  • 为何视觉对话式人工智能如今至关重要
  • 从机器人到 “生命体”—— 人机交互的转变

2. 逼真虚拟形象背后的核心技术

  • 实时行为建模

  • 语音合成与情感韵律

  • 面部动画与肢体动作


3. 具身化的力量 —— 声音、个性与存在感

4. 人工智能中的情感响应能力

5. 改变工作、学习与参与方式的应用案例

6. 信任因素 —— 为何逼真交互能带来更好的结果

7. 挑战与考量 —— 延迟、真实感、技术专业性

8. 未来是交互式的 —— 视觉对话式人工智能的愿景

演讲亮点

  • AI 正从文本交互迈向融合语音、表情等的多模态交互,技术让虚拟形象更逼真,改变人机互动模式。
  • 视觉对话式 AI 在工作、学习等场景作用显著,能通过情感响应和个性展现提升信任与效果。
  • AI 未来前景广阔,如何解决延迟、真实感及技术门槛等挑战。

听众收益

  • 能了解 AI 从文本交互到多模态交互的发展趋势,以及让虚拟形象更逼真的核心技术。
  • 可掌握视觉对话式 AI 在工作、学习等场景的实际应用价值,以及它如何提升交互效果。
  • 能清晰了解视觉 AI 的未来前景和当前面临的挑战,并对它的发展有更全面的认知。

交通指南

上海浦东滨江喜来登酒店

SHERATON SHANGHAI PUDONG RIVERSIDE
地址:上海浦东大道2288号
  • 微信咨询

  • 电话咨询

    联系电话:+86 18514549229

微信联系我们

如您在购票过程中遇到问题,请扫码咨询票务小助手